World-changing innovation tends to happen in two phases. The first is humanity figuring out how to unleash a powerful force (fire, electricity, computation). The second is learning to control it.
Print technology was around for eight hundred years before the Gutenberg press made it configurable enough that it could be used to efficiently disseminate knowledge. Humans studied wings and built gliders for over a century before the Wright brothers realized that the true unlock wasn't lift, but a three-axis mechanism for controlling pitch, roll, and yaw. And gunpowder had been used to create rockets and fireworks for seven hundred years before we learned to use gimbals to direct thrust, empowering humanity to not just leave Earth, but begin exploring new worlds.
Generative AI is no different. The first LLMs were completion models that, until they were post-trained to be conversational, generated seemingly random tokens. And the first four years of image generation has largely been spent in its "fireworks phase": pack as much material into a tube as possible, light it up, and hope to be entertained by whatever materializes.
With Reve 2.1, we set out to build the second phase.
Diffusion models generate beautiful images, but they're not overly intelligent or steerable. Autoregressive models (LLMs) are extremely intelligent, but they don't generate particularly aesthetic images, and latency makes creative iteration slow.
Reve 2.1 leverages the best of both worlds by separating planning from rendering. Reve images are meticulously laid out before being rendered to ensure that they are sufficiently detailed, and that each element is both correct and coherent. Not only does better planning lead to better images, but it also allows humans to inspect and participate in the planning process, as well as edit the layout in order to edit the image.
The concept of separating concerns is one of the most important architectural and cultural patterns ever discovered by humans. It enables specialization, abstraction, and flexibility. At Reve, we believe that the old way of generating images directly from text would be like generating entire applications without first generating a codebase. Going from prompt to binary without code in the middle would make the process slow, opaque, and almost impossible for the creator to meaningfully participate in.
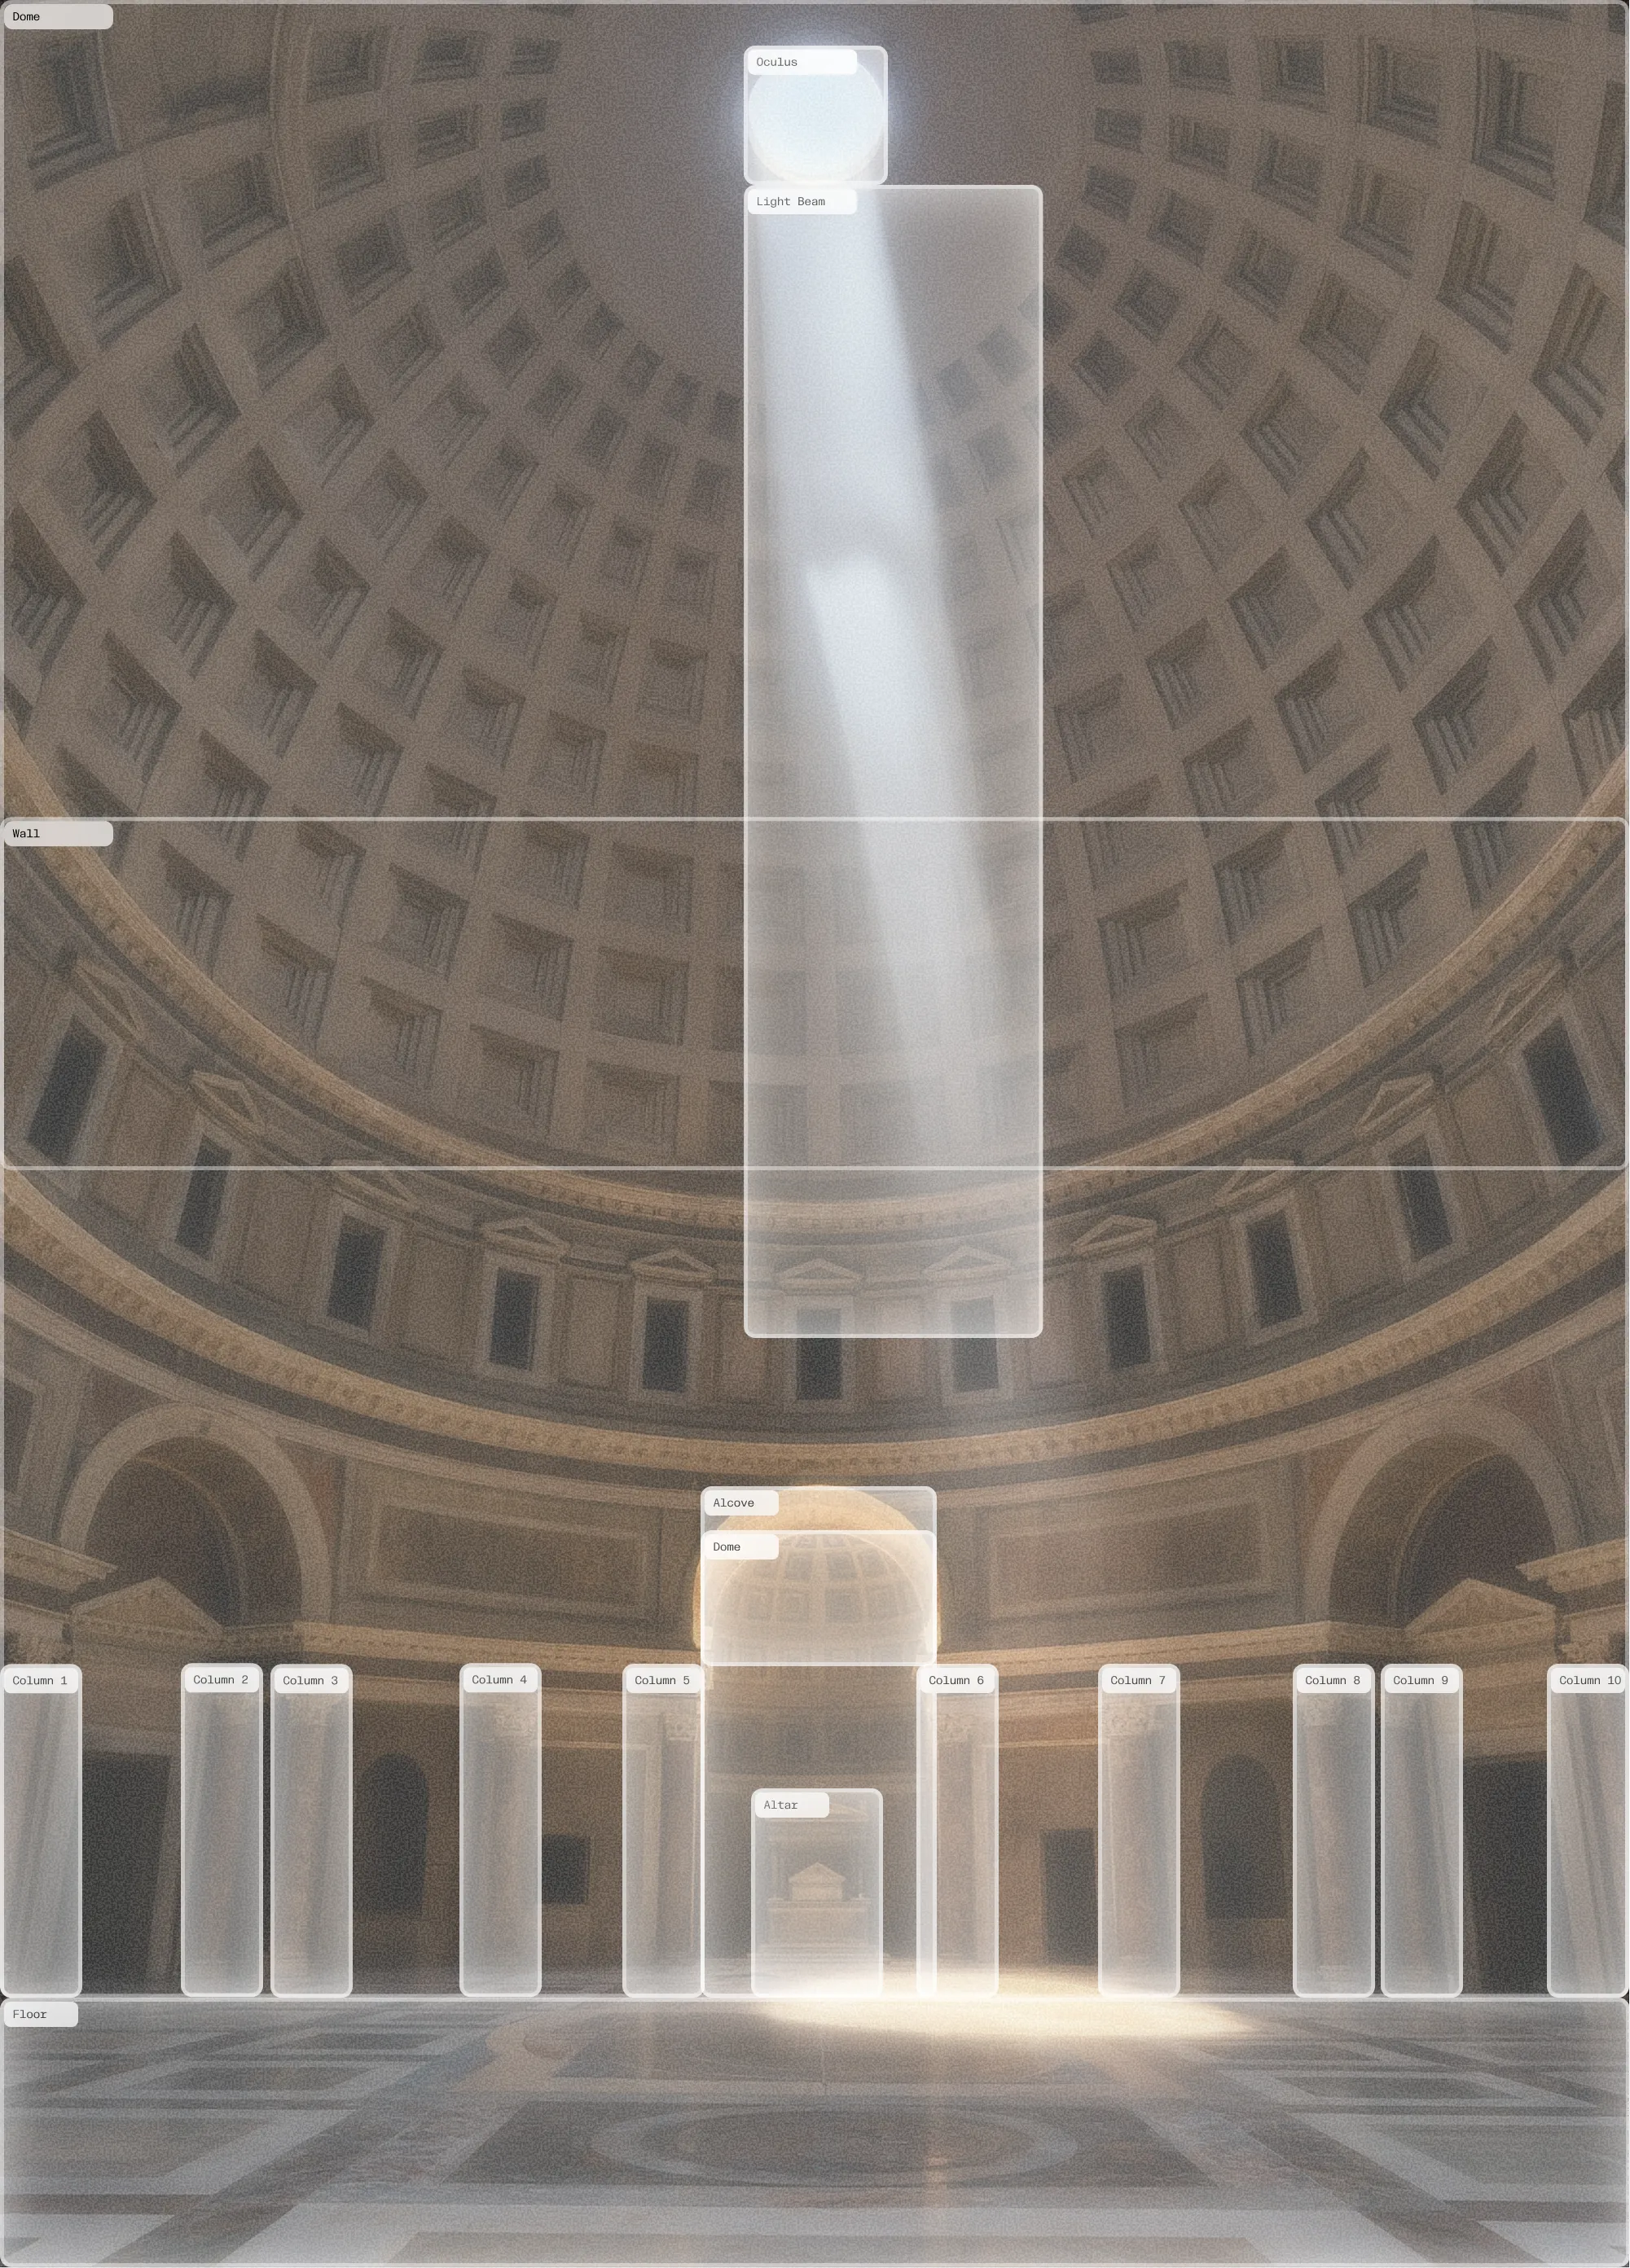
We believe code is the ultimate primitive, so to 'solve' digital images, we represented them as code.
Our previous model, Reve 1.0, was trained not on captions, but on detailed data structures that define composition, relationships, style, text, and more. It proved our hypothesis that simply expanding the "alt tags" that the first diffusion models were trained on into increasingly dense captions was not the optimal path toward fine-grained creative control.
But while Reve 1.0 proved the thesis, it also showed us that there was a lot more work to be done. The next step was to combine novel image planning and diffusion architectures with far more data, 3x the number of parameters, and more compute.
The results have exceeded our expectations. It is now clear that the key to both controllable image generation and editing is not denser prompts, but a highly detailed, highly manipulatable, intermediate representation expressed as code.
We've always believed in creative collaboration between humans and AI. The question in our mind was never if, but how. On the surface, it seems like having LLMs write and edit prompts for image generation models is like joining two gears that mesh perfectly: Language is what LLMs do best, and image models turn text into pixels.
But language is imprecise, full of nuance, highly subjective, and lossy. Additionally, creativity isn't a one-way workflow. It's inherently iterative.
Because Reve 2.1 images are code-based, they are agent-native, meaning agents can both "see" them and reason about them. But unlike other opaque agentic image generation and editing platforms, we can also build highly expressive, direct manipulation tools on top of the exact same intermediate representation.
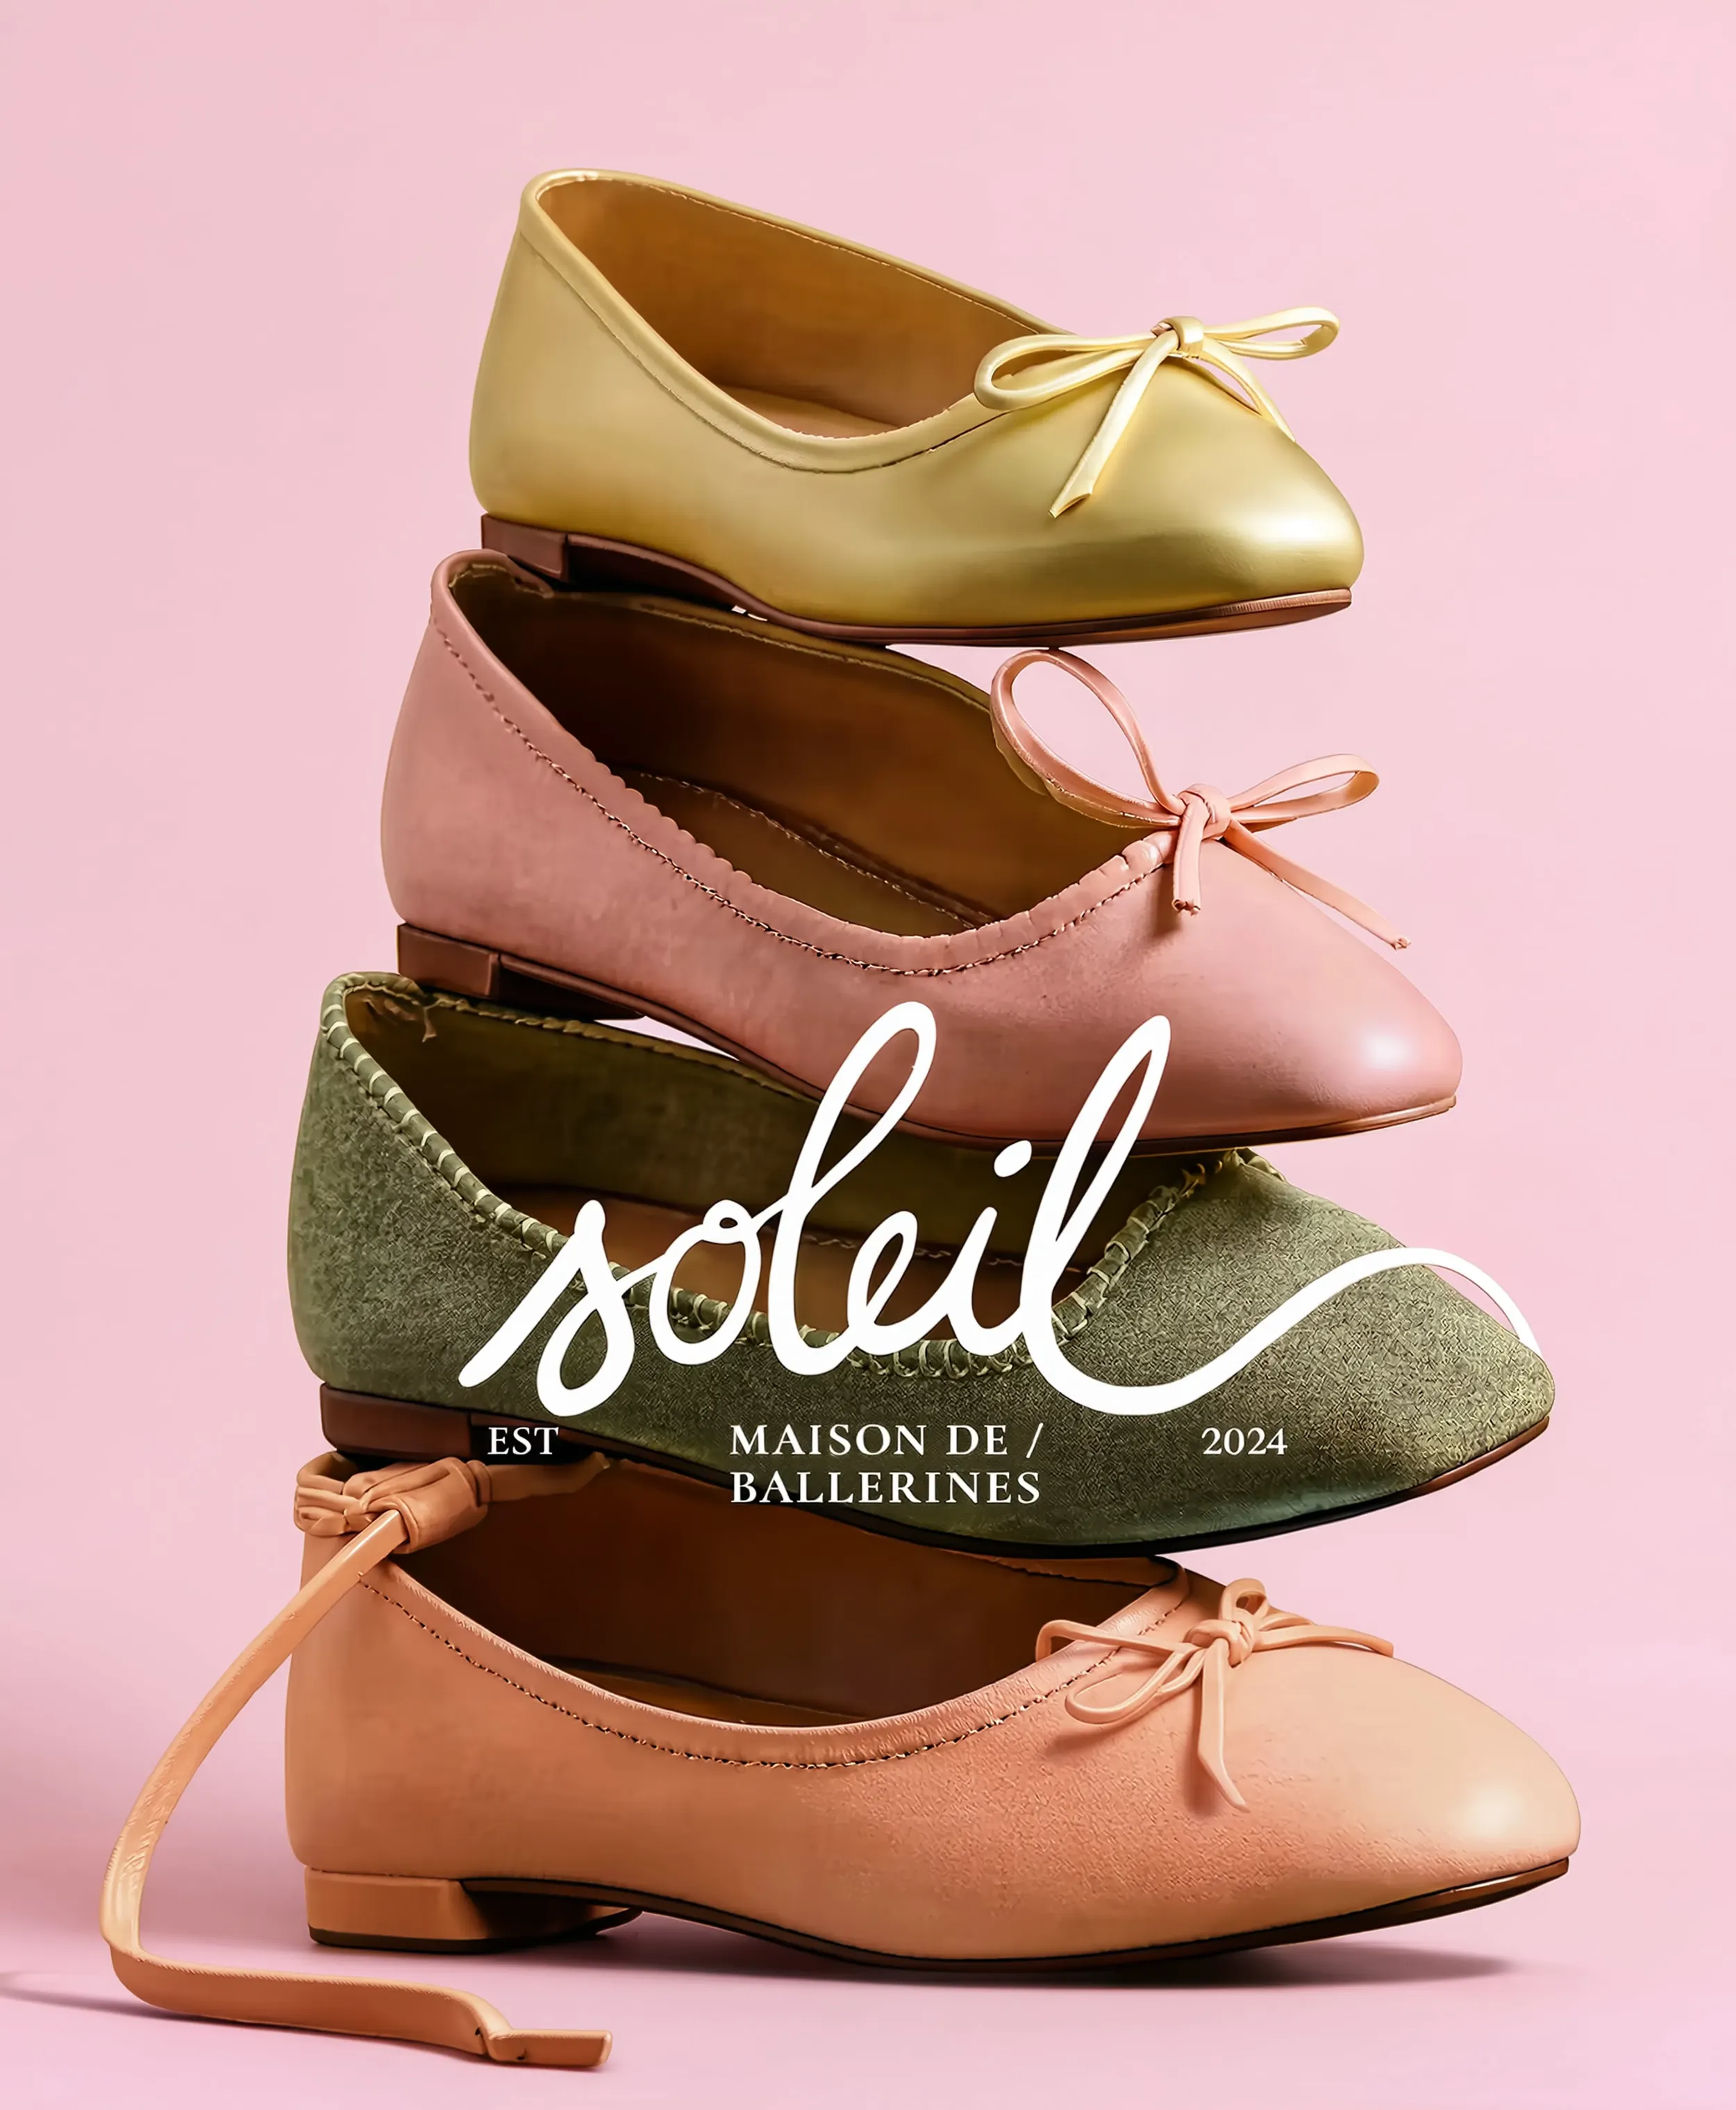
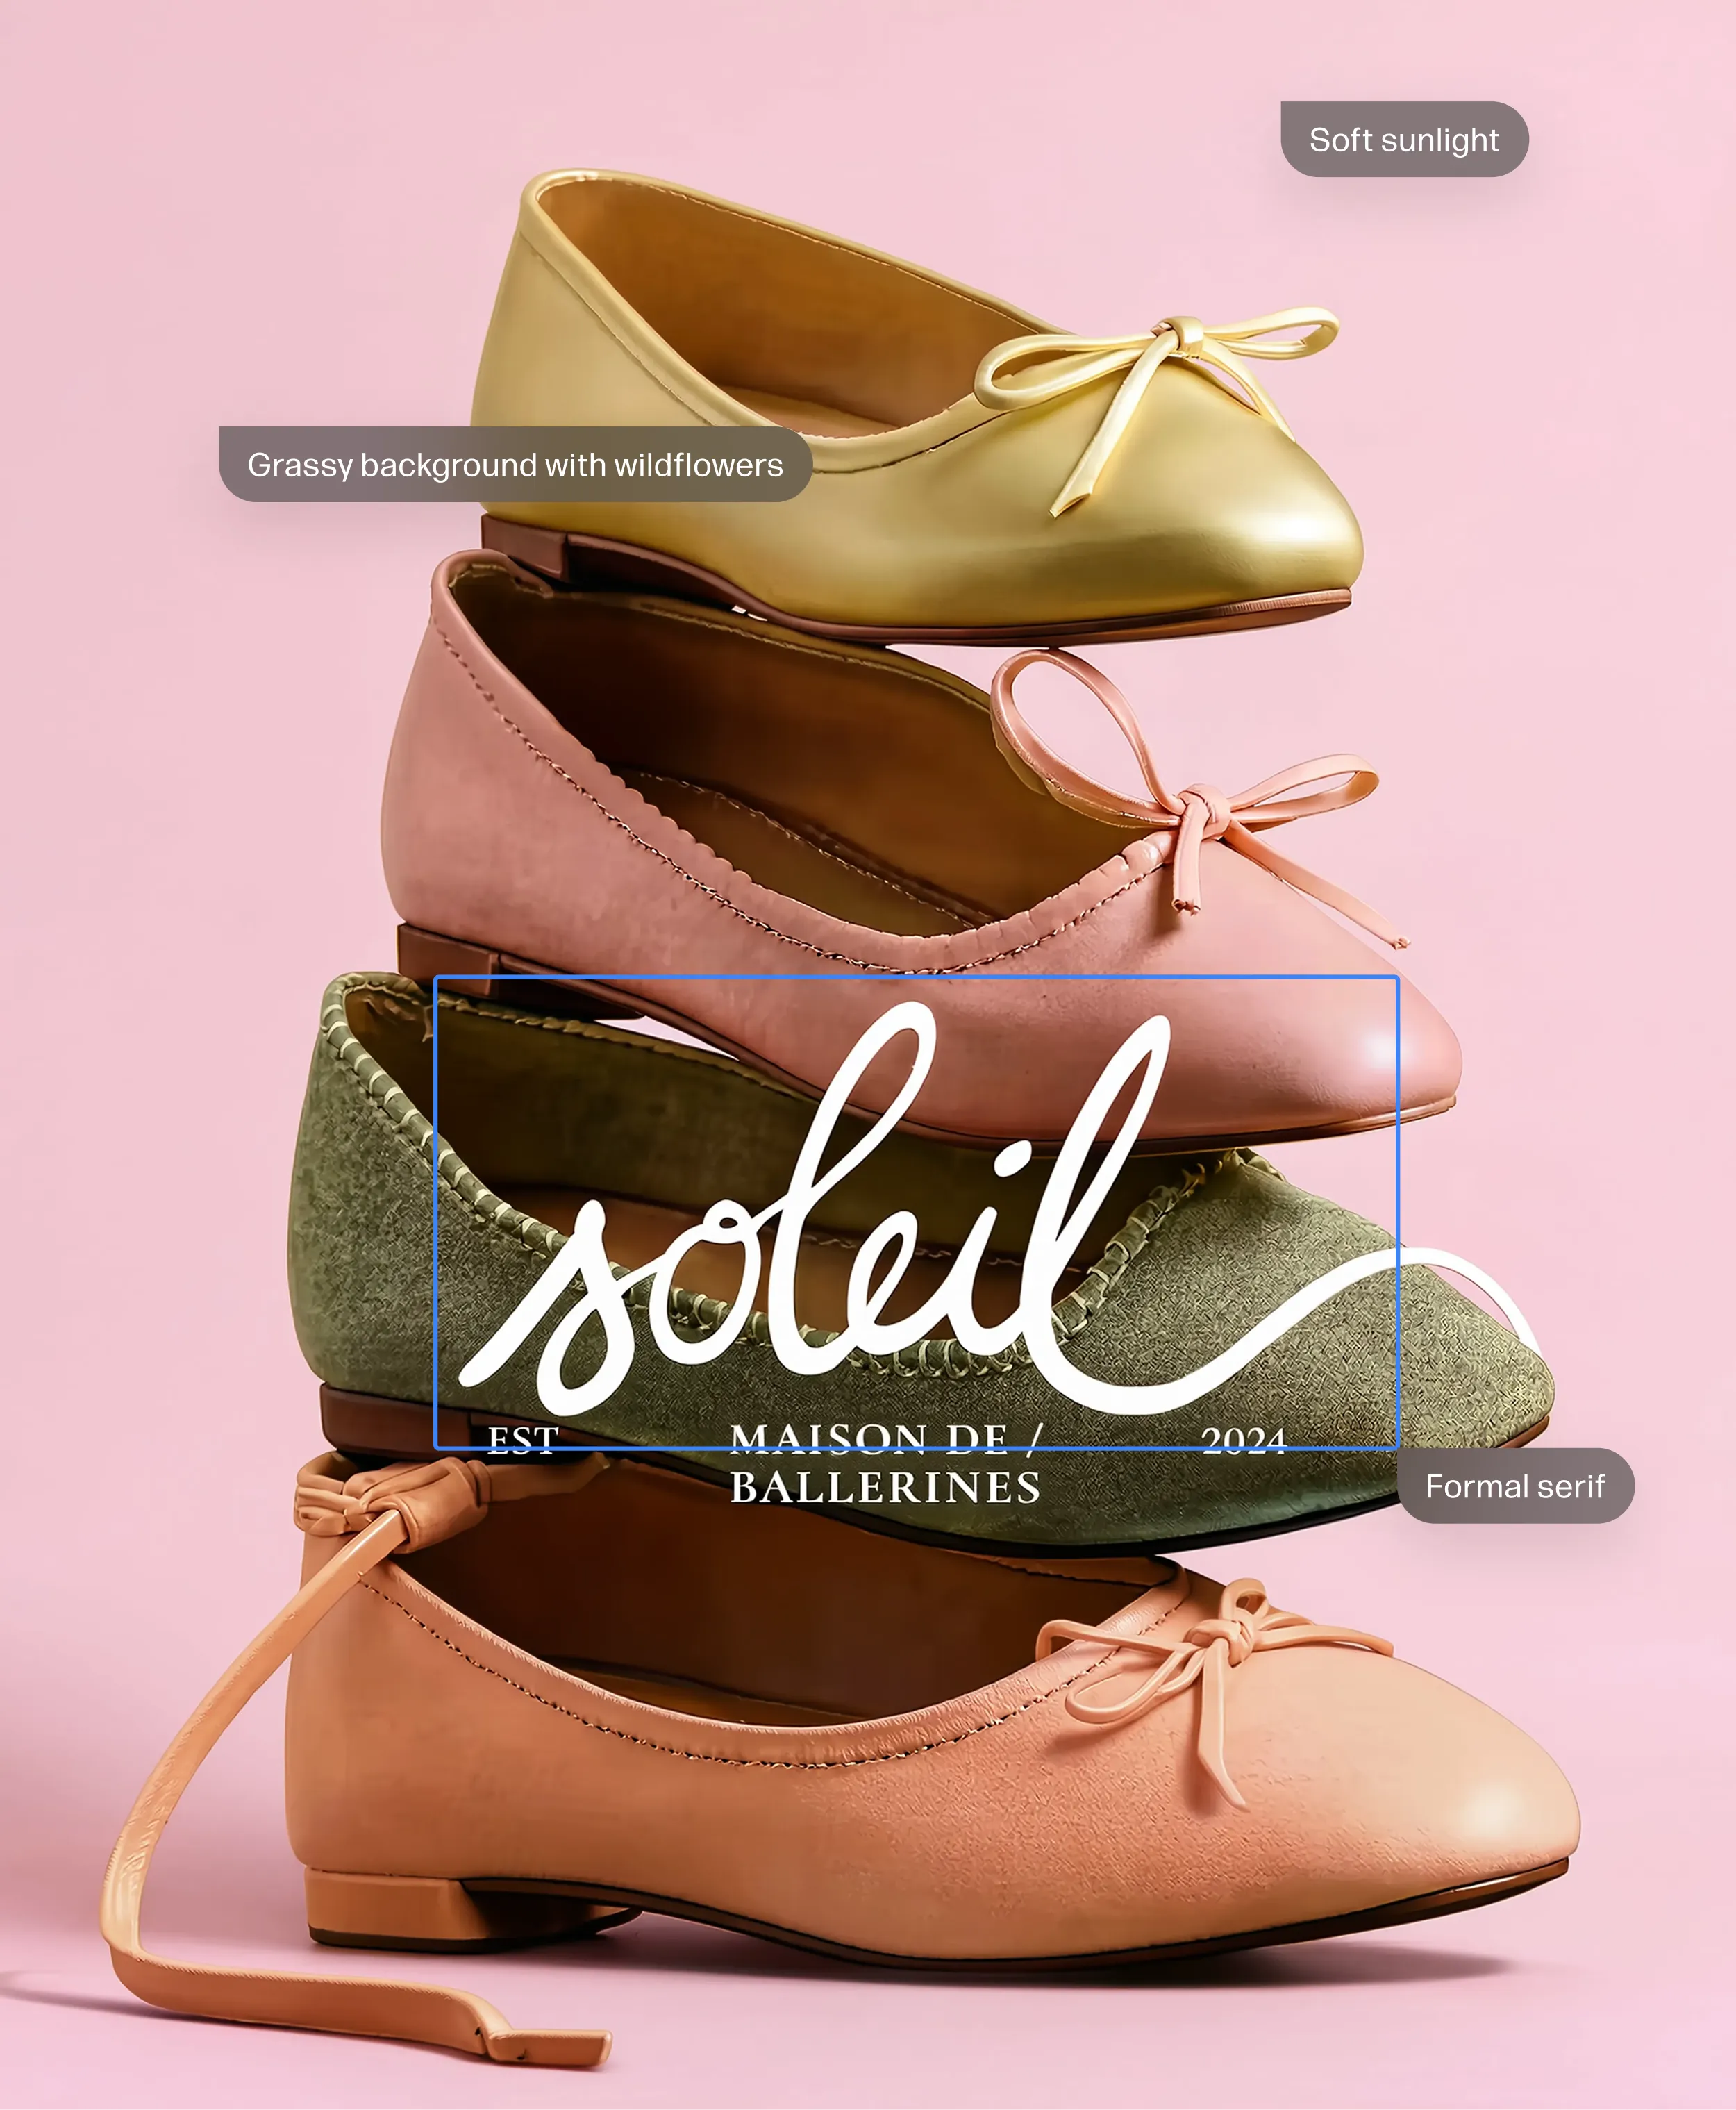
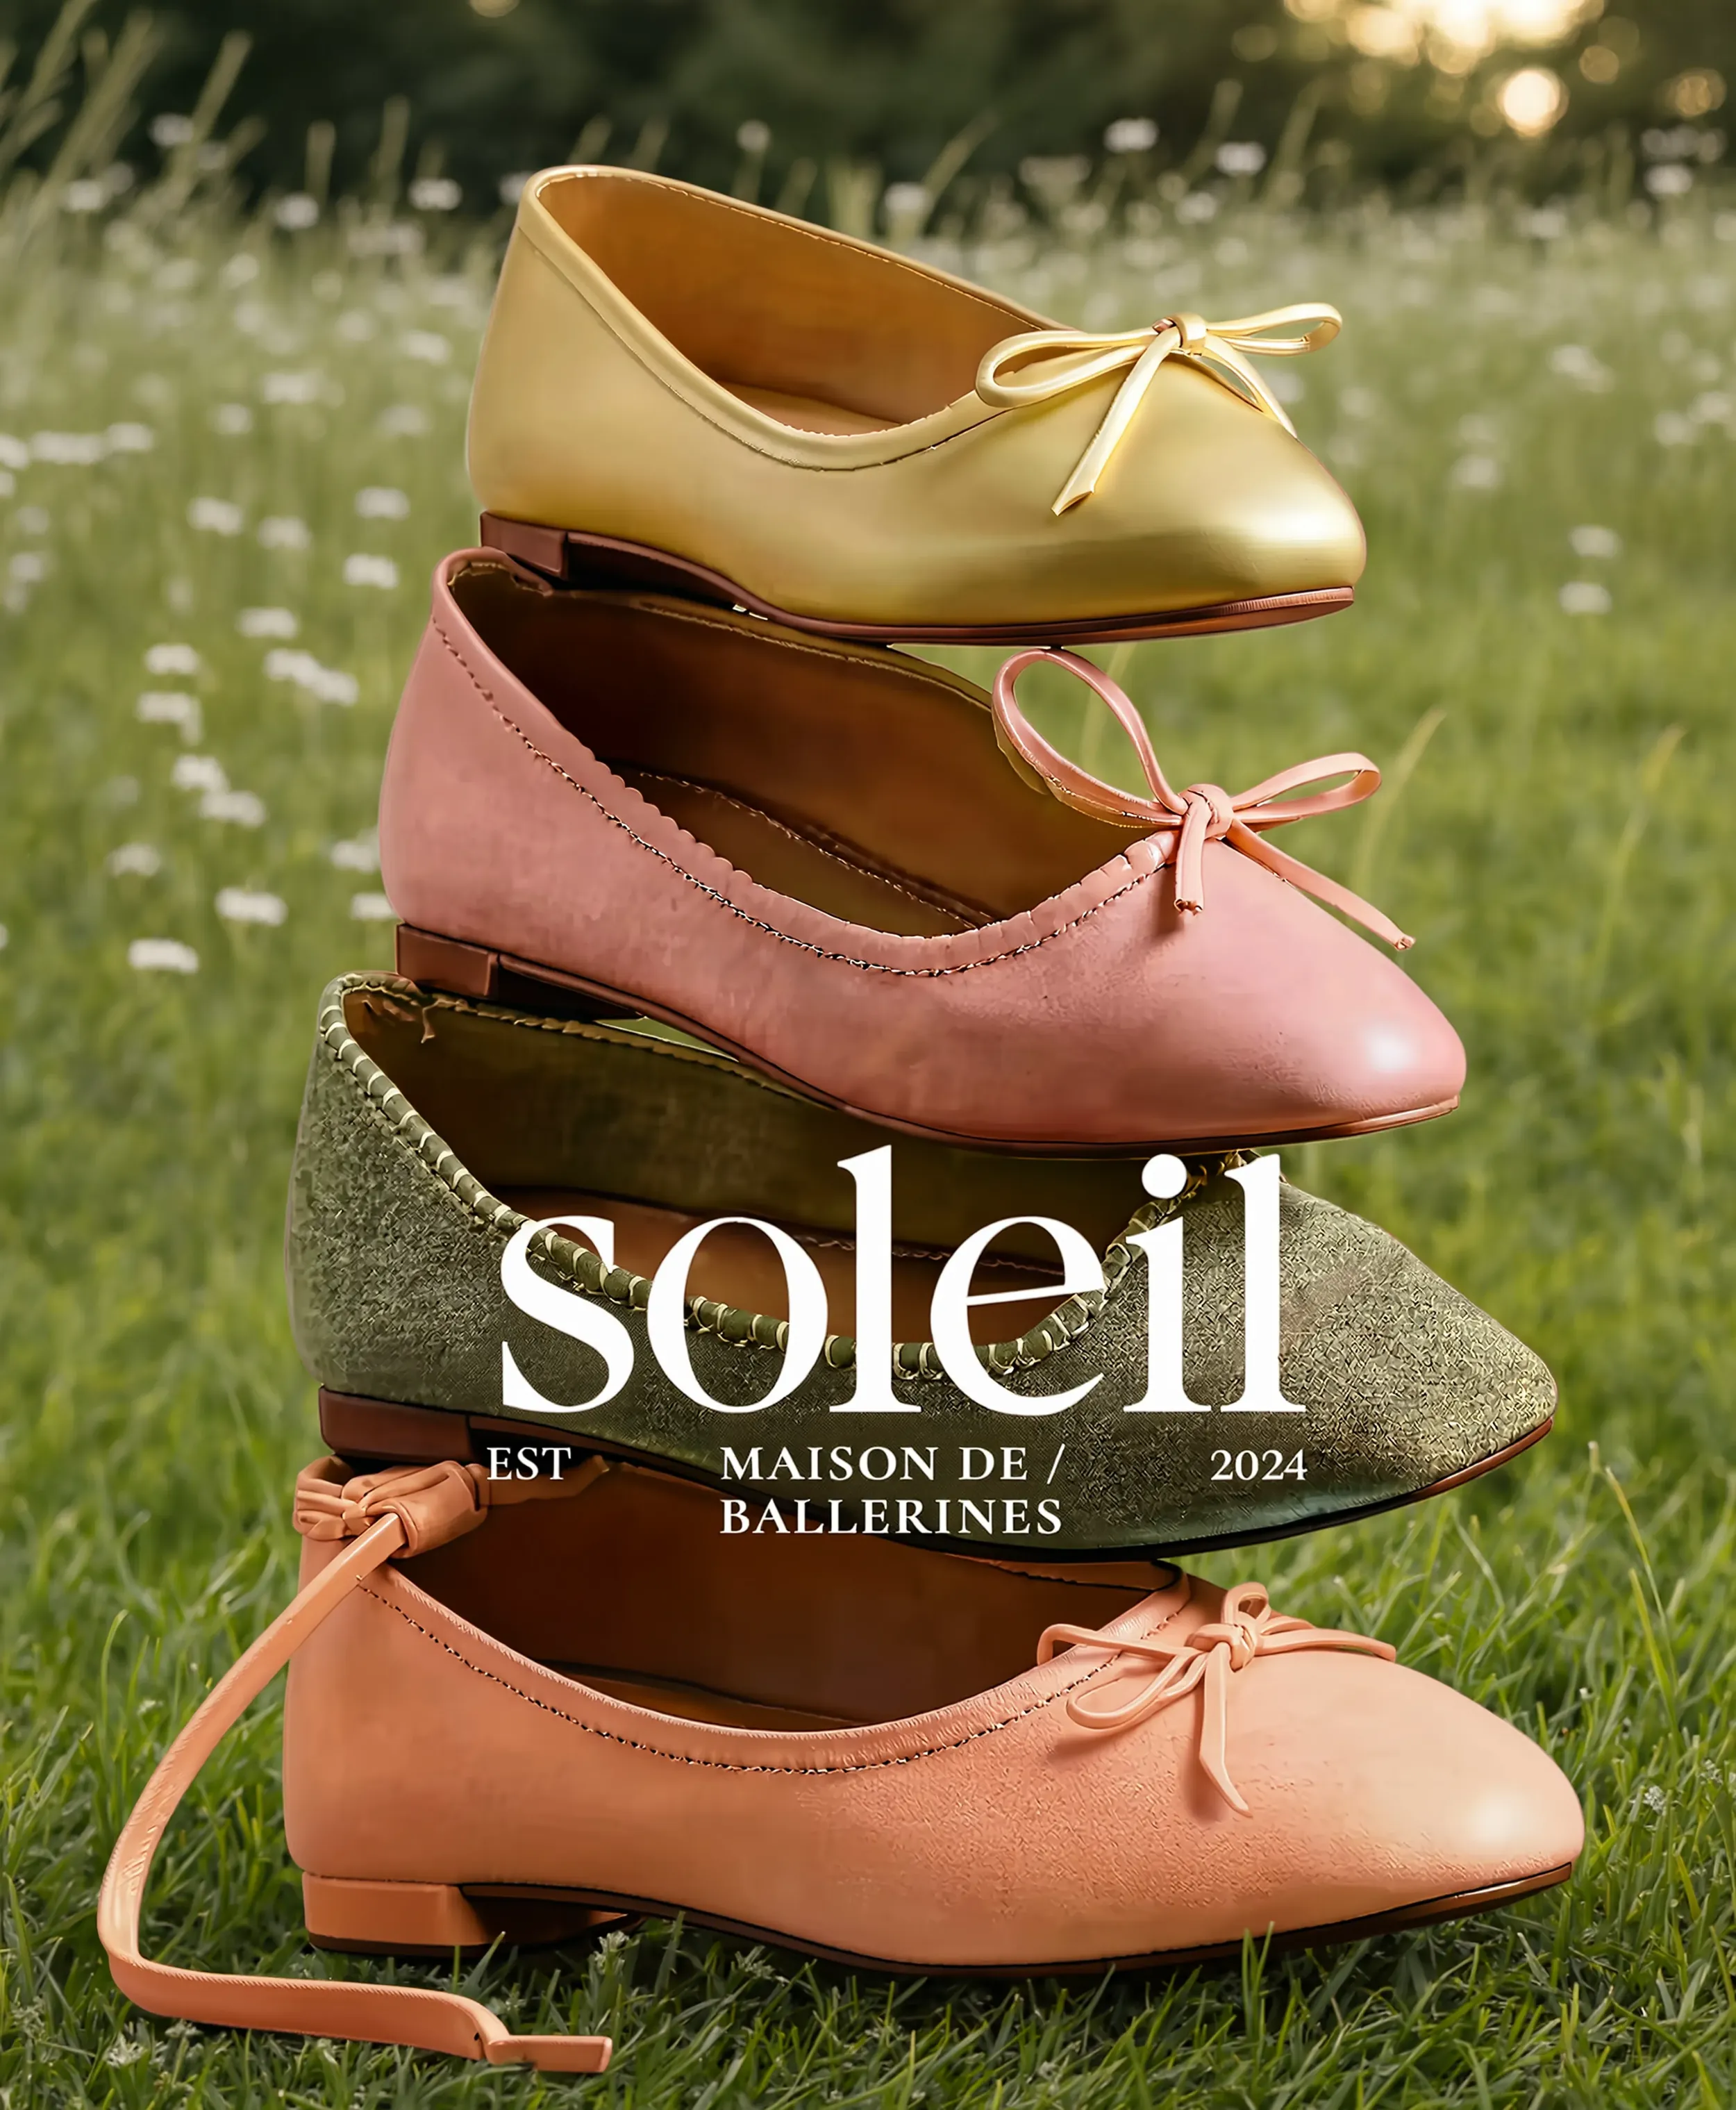
Reve 2.1 uses a novel and highly performant rendering architecture to generate images at native 4K x 4K resolution — true 16 megapixels. Not only is our renderer the fastest 4K image model in the world, but it enables a fundamentally different creative workflow.
Anyone who has spent time iterating on AI-generated images knows the frustration of finally getting an image exactly how you want it only to watch subtle details shift during upscaling. Upscaling can feel like one final dice roll after a long succession of dice rolls. The answer is not a separate upscaling step; it's to iterate at high-resolution, ensuring that what you see is truly what you get.
Working at high resolution matters both for digital work and for physical media. At 16MP, Reve 2.1 images are suitable for high-quality print workflows right out of the box. Rather than treating high resolution as a post-processing step, Reve treats it as a first-class primitive.
Iteration is at the core of every creative process. Creativity is not, and will never be, a one-shot workflow.
But modern image generation models punish iteration through progressive degradation. Each synthesized image contains diffusion and compression artifacts. When that image is reused as a reference image for another generation, those artifacts are carried forward, and a second layer of artifacts introduced. Over time, those artifacts do not just accumulate, but compound.
There are two ways that the Reve 2.1 model mitigates degradation:
Less degradation with image references. Reve 2.1 uses a novel rendering architecture designed specifically to resist this form of collapse. Image edits remain more stable through longer iterative workflows than other leading image models.
Zero degradation without image references. In the same way that running similar code results in similar output, generating images from code "locks image elements" providing much greater stability with no accumulation of artifacts whatsoever.
Reve 2.1 turns generative image editing into a proper iterative creative process.
Because Reve 2.1 represents images as code, text can be rendered with more explicit control. Composition, positioning, spacing, and relationships between elements are defined with far greater precision before the rendering process even begins.
Graphic design workflows in particular become dramatically more controllable. Text can be positioned exactly where it belongs within a composition. Layouts are not just coherent, but intelligent. And integrated environmental typography — handwriting, street signs, packaging, labels, menus, license plates — feels significantly less synthetic than what we typically see from other leading image models.
Reve 2.1 elevates high-quality text rendering from an evaluation checkbox to true and tasteful design.
AI generated images used to be identifiable by their plastic, excessively smoothed, and over-saturated appearance. While largely a thing of the past, modern AI images have developed a new tell: technical precision which lacks an aesthetic soul.
Since our Preview model in March 2025, Reve has been known for its distinctly cinematic, filmic, and photojournalistic aesthetic. By using code to plan images, we have been able to incorporate significantly more detail. Native 16MP resolution makes this effect dramatically more immersive. Lighting feels more natural. Spatial relationships become more convincing. Additional fine details emerge when zooming in.
Reve 2.1 was trained not just to render objects correctly, but to understand composition, framing, mood, atmosphere, and visual intention. The ability to explicitly control composition transforms the model from a generic image synthesizer into something much closer to a virtual camera and photo editor combined into a single creative workflow.
Alan Kay famously said that people who are serious about software should make their own hardware. At Reve, we believe the same principle applies to creativity.
With Reve 2.1, the model and the product were designed together from the very beginning.
Because images are represented as code, every part of an image becomes addressable, editable, and manipulatable. That foundation enabled us to build what we believe is the most powerful direct-manipulation editor for generative images ever created.
June 3, 2026.